The exact data model your fund needs
Suitable for any VC. A custom data model that fits how you operate.
Single source of truth infrastructure for VCs — tailored scraping, unified data, zero maintenance burden.
Alpha won't come from buying the next data source and connecting it to Claude. VCs generate alpha by fusing public data, tailored to you with your proprietary data into compounding institutional knowledge.
Suitable for any VC. A custom data model that fits how you operate.
Highly scalable web scraping and web search gives you the startups, signals and context your fund needs.
Meeting transcripts, IC memos, and decisions only become valuable once the data behind them is structured.
Researchly catches, explains, and if you want also resolves data quality issues for you.
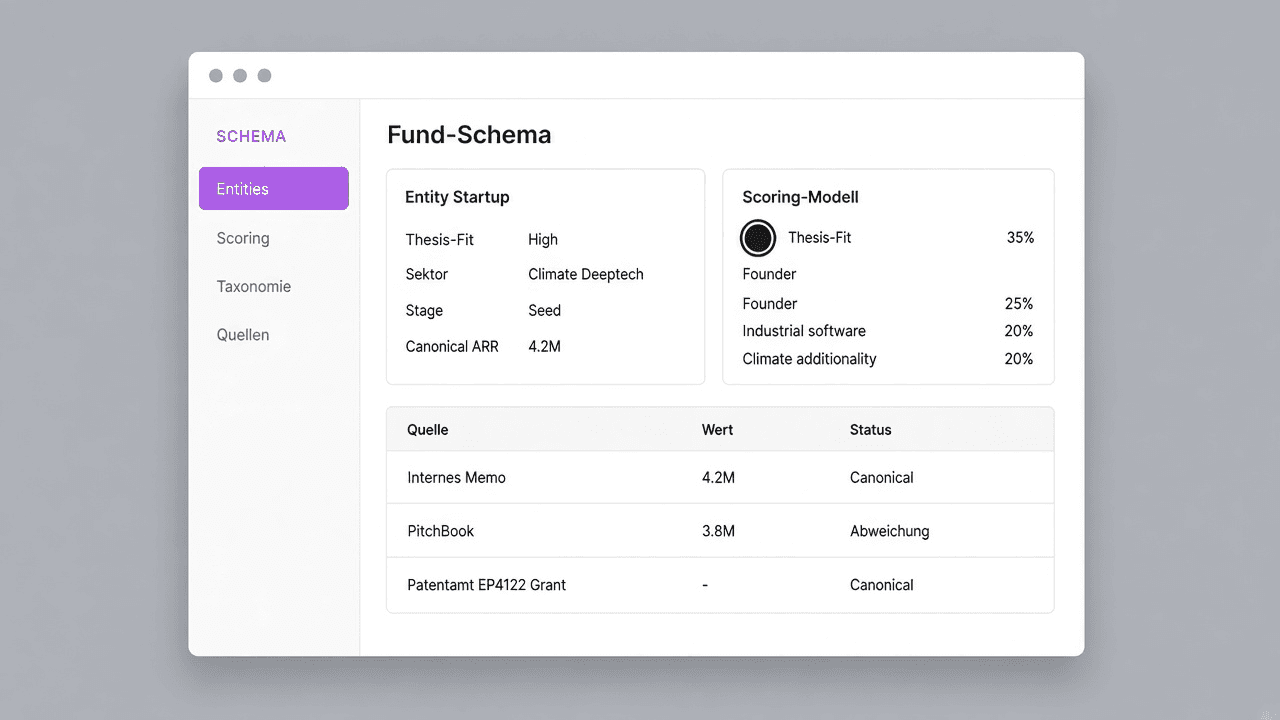
Custom data schema per fund, centered around business objects and fine-tuned with custom attributes create a data foundation to fit your funds needs - not the other way around.
Our Business Objects-oriented infrastructure ensures you can easily reconcile multiple data sources without changing the infrastructure
Each table is fully historized so you never lose an entry. Each entry comes comes with full data lineage.
Our data warehouse is built so that you can combine any data source - proprietary or 3rd party - at ease.
Researchly catches, explains, and if you want also resolves data quality issues for you.
Entity resolution
Sources contradict each other.
with our matrix
Turn unstructured data into structured
Datenquellen //
Offene Webquellen, Premium Quellen und proprietäre Datenbanken - sauber aufbereitet mit Deduplizierung, Entity Resolution und Clustering.
| Offenes Web | Premium Quellen | Proprietäre Datenbank | |
|---|---|---|---|
WSPararelle Research Agents für Deep Web Search | PAPatente | ASAlternative Signale für Firmen (M&A-Aktivitäten, Produktankündigungen, Partnerschaften…) | CDFirmendatenbank |
NBNachrichten, Blogs & Foren | FFEarnings Calls und Jahresabschlüsse | MDMarktreports | TBTrenddatenbank |
WDWeb Data (Google, YouTube, Amazon) | FBÖsterreichisches Firmenbuch | MDStartup-Datenbank | |
WDWeb Scraping | |||
WDJobausschreibungen & Firmenwebsite | |||
Fallstudie //
Strategieabteilung, österreichisches Infrastrukturunternehmen
(>10.000 Mitarbeitende)
„Wir mussten unsere Methodik nicht ändern. Wir brauchten einen Weg, um unsere Methode zu skalieren.“
Die Herausforderung
Das Technologieradar entstand in Handarbeit: zehn Publikationen wöchentlich lesen, jeden Beitrag klassifizieren, nach Marktreife und Relevanz clustern, monatlich im Vorstand präsentieren.
Der Prozess war sauber. Nur skalierte er nicht.
Das Ergebnis
10x
Mehr ausgewertete Quellen
Die bestehende Taxonomie blieb unverändert - Radar ist laufend aktuell statt wöchentlich nachgeführt.
Fallstudie lesen→Trust //
EU-Datenhaltung
Kundendaten werden in der Europäischen Union gespeichert und verarbeitet.
Quellennachweis
Jede Aussage ist mit öffentlicher Dokumentation und nachvollziehbaren Quellen belegt.
Kein Training mit Kundendaten
Ihre Daten werden nicht zum Training von Modellen verwendet und nicht an Drittanbieter-KI weitergegeben.